AI Development & Machine Learning Services
Transform your enterprise data into competitive intelligence. We build custom LLMs, Generative AI agent workflows, computer vision, and predictive ML models engineered for scalable production impact.
Production-Ready AI & LLM Architecture
We don't just wrap basic API calls. We architect enterprise-grade AI backbones with private vector stores, multi-agent swarms, PII guardrails, and self-hosted inference engines.
Hybrid RAG & Vector Memory
Ground LLM responses in your private enterprise documentation, databases, and APIs without hallucination.
Vector DB Indexing
Qdrant, Pinecone, Milvus, and pgvector with hybrid dense + BM25 keyword search.
Context Chunking & Reranking
Semantic chunking and Cohere Rerank models for highest relevance.
Multi-Source Connectors
Real-time sync with Salesforce, Notion, SQL databases, Confluence, and S3 buckets.
// Syntor Enterprise RAG Pipeline (LlamaIndex + pgvector)
const vectorStore = new PGVectorStore({ connectionString: DB_URL });
const retriever = new VectorIndexRetriever({
  vectorStore,
  similarityTopK: 5,
  reranker: new CohereRerank({ topN: 3 })
});
const response = await retriever.synthesizeQuery({ query, userRole });Real-World AI & ML Case Studies
Three engagements showing how our custom AI models deliver measurable operational savings, sub-15ms inference, and sovereign data residency.
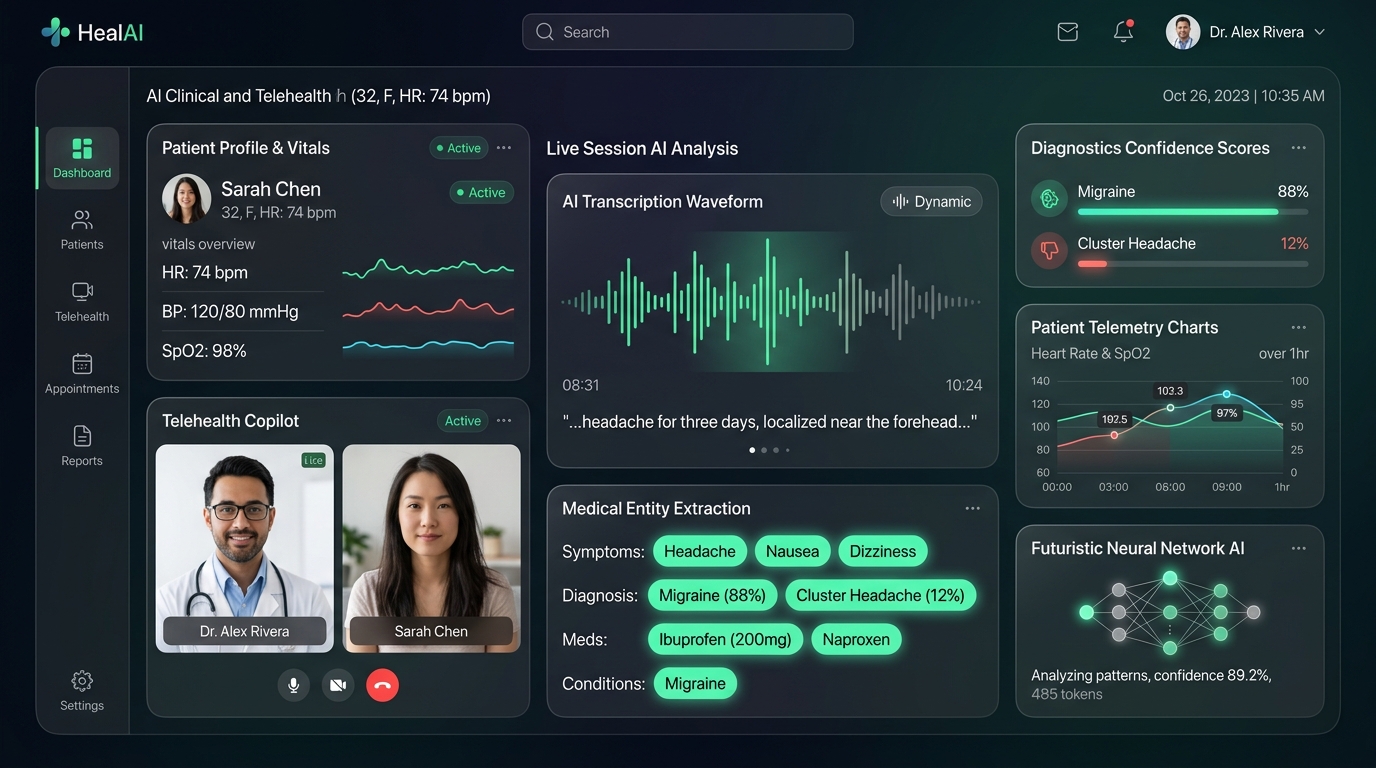
MediVoice: AI Clinical Note Generation & EHR Sync
Physicians spending 3+ hours per day manually documenting patient notes into EHR software, causing clinician burnout and billing delays.
Engineered an ambient voice AI platform that listens to doctor-patient consultations, generates structured SOAP medical summaries, and maps ICD-10 codes directly into hospital EHRs.
When Custom AI & LLM Systems Beat Generic AI Wrappers
Superficial OpenAI API wrappers hallucinate, leak sensitive corporate data, and cannot reason over your complex private business documents. Custom enterprise AI embeds domain-specific fine-tuning, deterministic RAG pipelines, and strict guardrails that make intelligence repeatable and auditable.
Enterprise Vulnerabilities
Total Algorithmic Control
Comprehensive AI & Machine Learning Capabilities
From exploratory PoCs to enterprise-scale autonomous AI agents, we engineer reliable, hallucination-resistant AI systems that solve complex business problems.
Generative AI & LLM Fine-Tuning
Customizing foundation models (OpenAI, Claude, LLaMA) with proprietary domain data, Retrieval-Augmented Generation (RAG), and vector databases.
Autonomous Multi-Agent AI Systems
Engineering specialized AI agent teams that autonomously research, execute multi-step operational workflows, and verify outputs with human-in-the-loop controls.
Predictive Analytics & ML Forecasting
High-accuracy time-series forecasting, demand modeling, customer churn prevention, and anomaly detection models trained on historical data.
Computer Vision & OCR Automation
Automated visual inspection, facial biometric recognition, document layout parsing, and real-time video stream object detection.
Natural Language Processing (NLP)
Multilingual sentiment analysis, intent categorization, automated contract parsing, and domain-specific intelligent chatbots.
Enterprise AI Integration & MLOps
Productionizing machine learning models with automated CI/CD retraining pipelines, low-latency API inference, and continuous drift monitoring.
AI Engineering Engagement Models Built For Real Impact
Whether you need a 3-week AI feasibility spike, a dedicated LLM product squad, or senior ML engineer augmentation, we have models built for high-stakes intelligence.
AI Feasibility & PoC Sprint (2–4 Weeks)
A rapid, low-risk sprint where our AI architects ingest a sample of your enterprise data, benchmark candidate models, and deliver a working interactive prototype with verifiable metrics.
Send Your AI Brief. See a Functional AI Prototype in 48 Hours.
Send us your problem statement and sample data. Get an architectural feasibility analysis, prompt pipeline blueprint, and interactive prototype reviewed by our senior AI researchers.
We build across every modern stack
Our engineers pick the right tool for your product, not the other way around.





Our 8-Step AI Engineering Lifecycle
From data ingestion and benchmark evaluations to private VPC cloud deployment and continuous MLOps telemetry.
Demand & Problem Analysis
A business analyst and tech lead review your brief, market context, and end-user requirements.
Terms of Contract Discussion
We finalize project scope, engagement model, milestone pricing, and compliance terms.
Conception & Architecture Prep
Dedicated PM, tech lead, and cloud architect map the project, allocate team pods, and draft risk management strategies.
Project Kick-Off
Joint kickoff with your team to align on RACI matrix, communication cadence, and the first sprint goals.
Agile Software Engineering
Sprint cycles with AI-assisted code generation, protected repos, and bi-weekly demoable increments.
Quality Assurance & Automated QA
Automated CI/CD testing - functional, regression, security, performance, and accessibility checks.
Production Software Deployment
Zero-downtime release to your AWS/Azure cloud with documented rollback procedures and live telemetry.
Launch & Continuous SLA Support
24/7 SLA-backed incident response, security updates, performance tuning, and continuous feature delivery.
Frequently Asked Questions About AI
Clear answers on model hallucination mitigation, private VPC data residency, fine-tuning costs, and GPU compute allocation.
Generic APIs provide broad, general knowledge and send your queries to external third parties. Custom AI development fine-tunes models on your proprietary company data, connects to your internal databases through RAG, respects user permission roles, and runs securely within your private cloud.
Have a unique technical question?
Speak directly with our senior solutions architect, not a sales representative.
Let's discuss your needs!
The Syntor IT Advantages
Head Office